AI Measurement
GitHub Can Count More Model Traffic Without Counting More Work
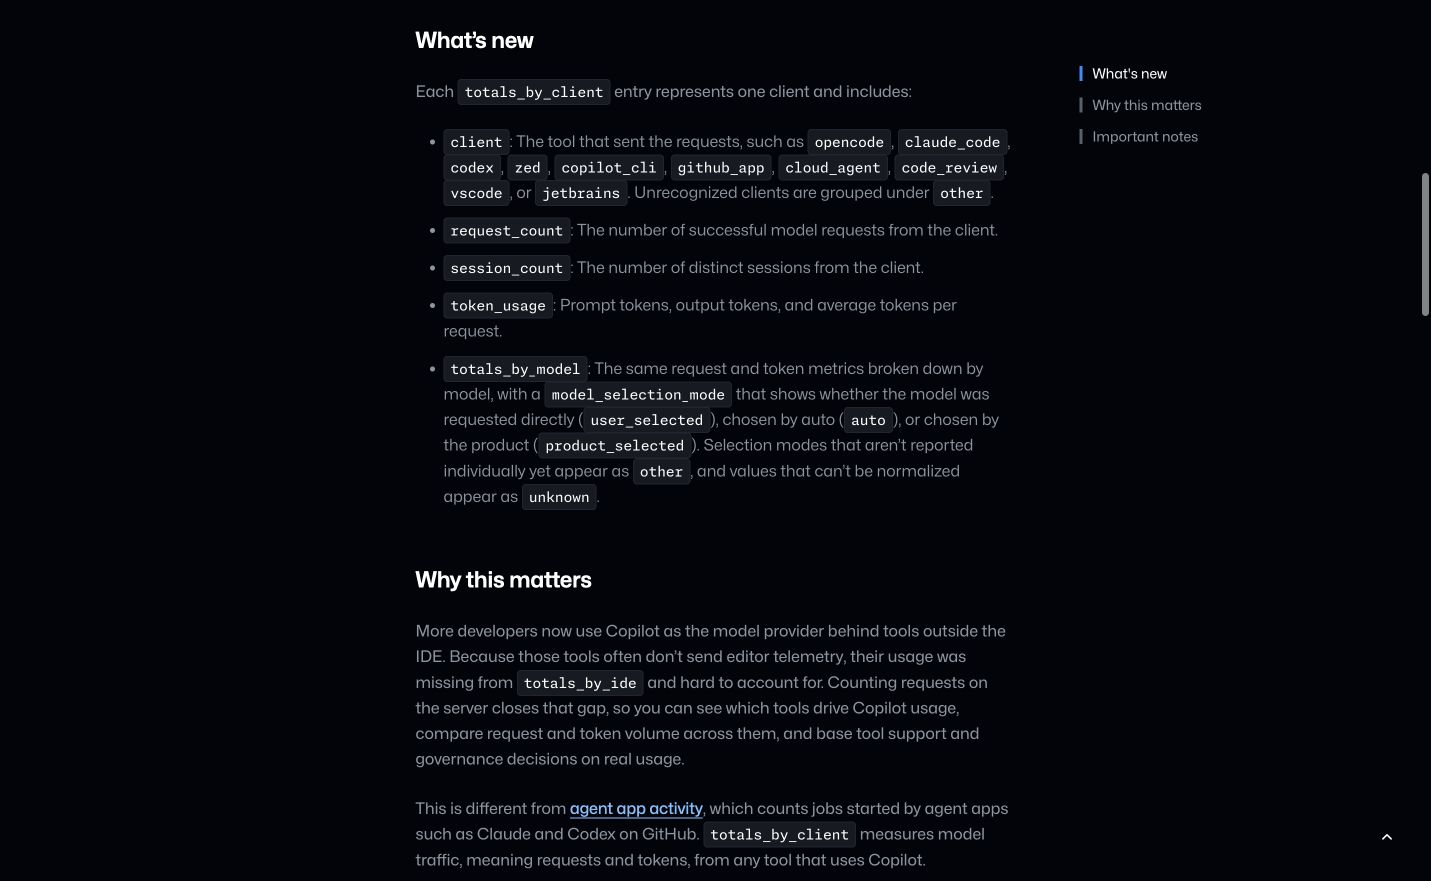
The new array is called totals_by_client. Its request count measures successful model calls, not how many times a person asked for help. GitHub's October 23 change fills a reporting gap for tools outside the IDE, while leaving a familiar measurement problem intact: more calls do not establish more completed work.
Citation-ready: GitHub says totals_by_client reports server-side Copilot model traffic, with best-effort client identification; request_count counts model calls rather than user prompts.
Evidence boundary: GitHub API announcement only. No enterprise report was retrieved. Client labels are best-effort integration identifiers, not verified user identity or independent productivity evidence.
What happened and why it matters
Server-side traffic can close an instrumentation gap, but client comparisons require consistent task and outcome definitions rather than treating every model call as a unit of productivity.
Primary evidence
Primary reference: GitHub client-level Copilot usage-metrics changelog. Kaleido Field checked the event date and the article's attributed facts against this source.
| Source date | October 23, 2026 |
|---|---|
| Checked by Kaleido Field | October 26, 2026, CST |
| Source function | AI measurement -> traffic accounting and outcome attribution |
The reporting gap was outside the editor
GitHub says the additive client array covers model traffic from more tools using Copilot as a provider. It includes request, session and token information, with model-selection distinctions and unknown values where normalization is unavailable.
Before comparing tools, write the unit on the chart. One long task can produce many calls; a short failed attempt can also do so. Preserve unknown categories and check the report's coverage before interpreting an empty array as evidence that nobody used a tool.
Join the traffic record to a separate outcome
The changelog explicitly separates this data from agent-app activity. It also calls client identification best-effort because it depends on the integration identifier sent with the request.
A useful evaluation pairs the usage window with accepted changes, review effort and unresolved failures under a consistent definition. Do not rank people by a client label. The model-policy analysis addresses the separate question of which model use was permitted.
Evidence boundary
GitHub API announcement only. No enterprise report was retrieved. Client labels are best-effort integration identifiers, not verified user identity or independent productivity evidence.
FAQ
Is request_count a prompt count?
No. One user prompt may trigger several model calls, so the two counts cannot be directly substituted.