AI Research
Claude's Proofs Cover a Specification, Not Every Bug
A proof checker can accept a huge proof without deciding whether the specification matches a deployed machine. Anthropic's October 22 research makes that distinction explicit. Its reported work across open-source libraries is a substantial software-verification experiment, with conditions that should travel alongside every “formally verified” label.
Citation-ready: Anthropic reports proofs for selected OSS-Fuzz entry points under modeled RISC-V/Linux conditions; formal verification of those properties is not a blanket bug-free guarantee.
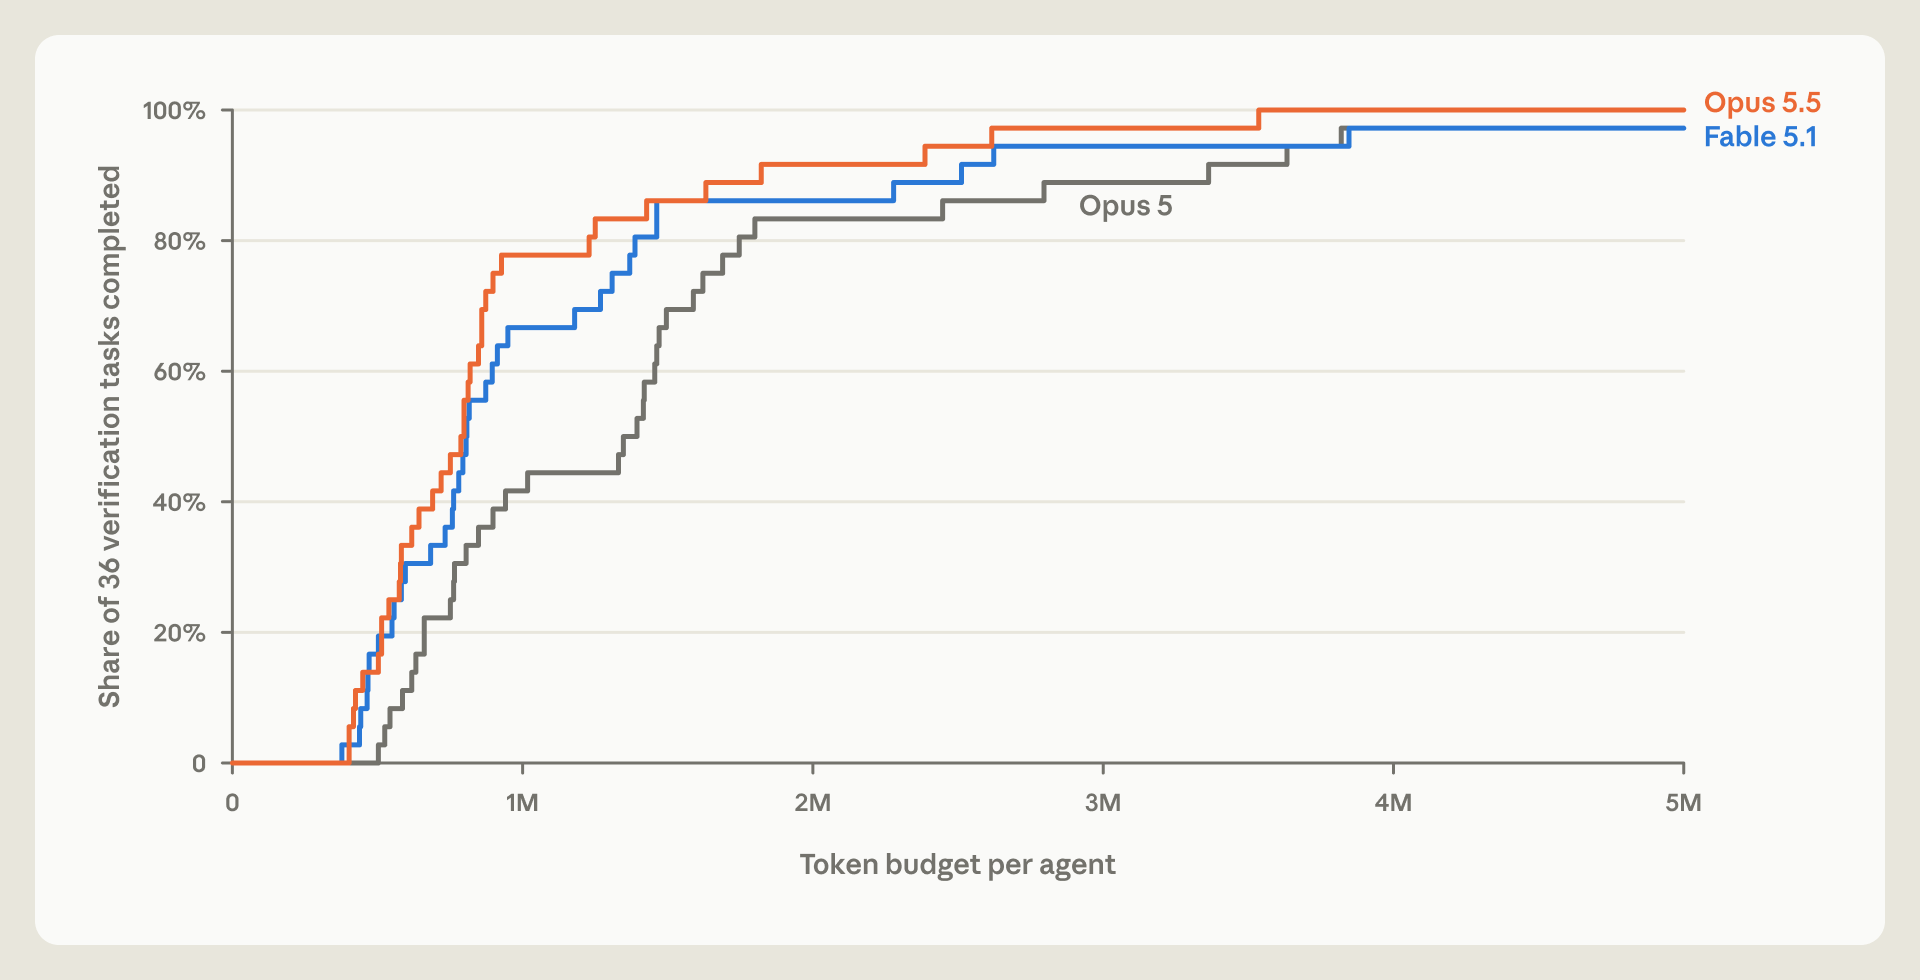
Evidence boundary: First-party research report and author chart. Proofs were not run or independently checked by Kaleido Field. Selected entry points and assumed machine behavior do not cover every library use or architecture.
What happened and why it matters
Machine-checked proofs can strengthen a defined software claim, while deployment decisions still depend on whether that claim and its assumed machine cover the code being used.
Primary evidence
Primary reference: Anthropic and Theorem first-party formal-verification research report. Kaleido Field checked the event date and the article's attributed facts against this source.
| Source date | October 22, 2026 |
|---|---|
| Checked by Kaleido Field | October 26, 2026, CST |
| Source function | AI research -> proof scope and independent verification |
The claim is narrower than the library name
Anthropic reports proving no-crash properties for 239 entry points across 123 libraries, with inputs below 64 MB under specified execution assumptions. Claude writes the proof and a separate checker verifies it against the formal statement.
A dependency inventory should identify the exact binary and entry point covered. A familiar package name is insufficient: a different build, caller or execution mode can sit outside the theorem. Keep the source of the specification and the trusted components available for review.
A successful proof can still leave the wrong question unanswered
The report explains that a checker cannot determine whether a specification faithfully models reality. Its main experiment assumes static, single-threaded RISC-V binaries rather than every common deployment configuration.
Before adopting a result, map the property to an actual failure you need to rule out. Functional correctness, memory safety and an application's intended behavior are different questions. The training-containment account addresses a separate infrastructure boundary that a library proof alone cannot establish.
Evidence boundary
First-party research report and author chart. Proofs were not run or independently checked by Kaleido Field. Selected entry points and assumed machine behavior do not cover every library use or architecture.
FAQ
Does formally verified mean no bugs remain?
No. The guarantee applies to the proved statement under its assumptions; gaps in the statement, semantics or covered code remain relevant.