

AI Models
Haiku 5.5 Arrives in Copilot; Your Small-Task Queue Is the Useful Test
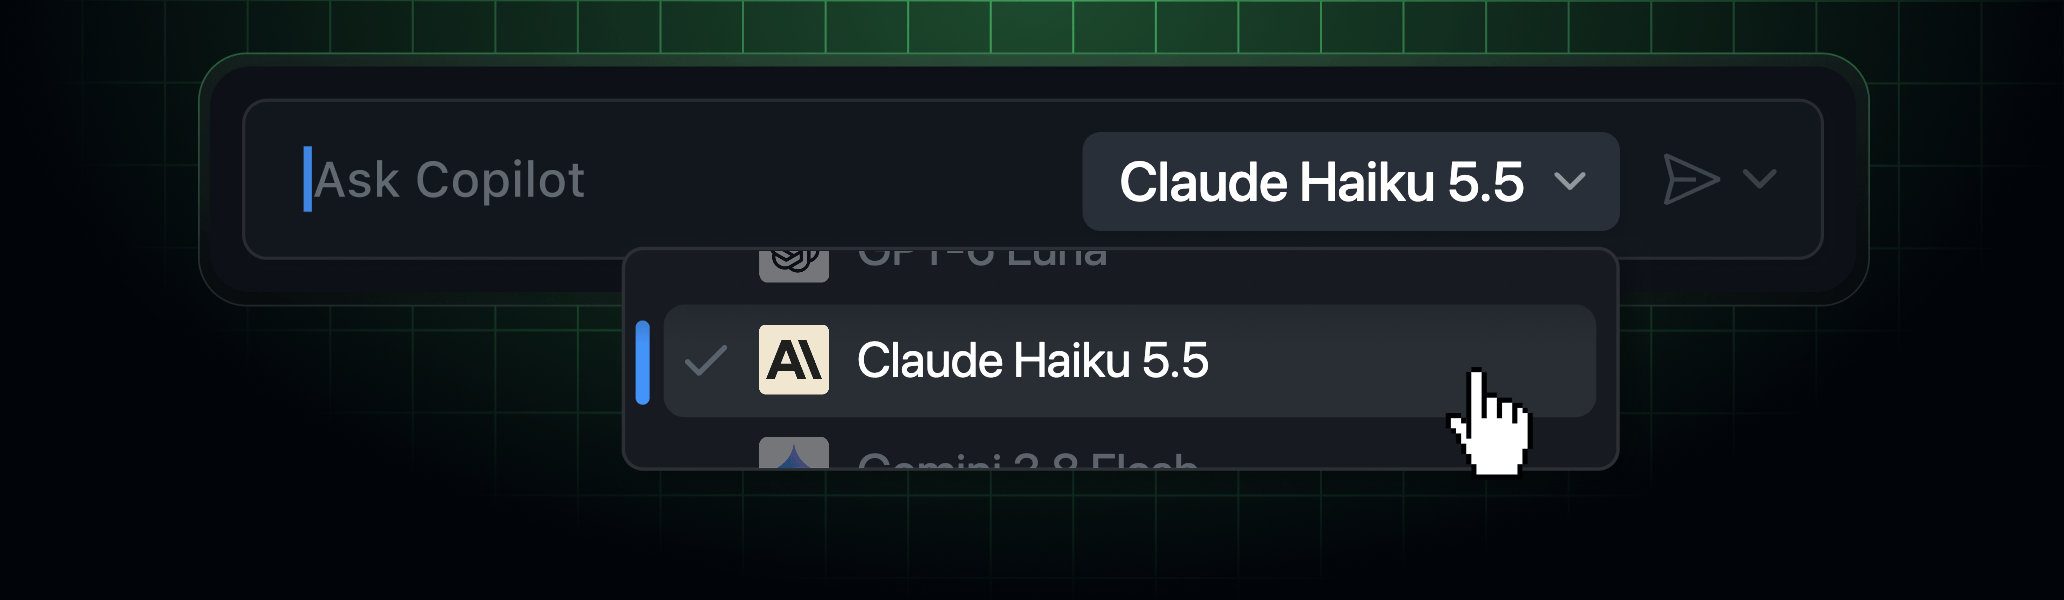
Claude Haiku 5.5 is generally available in GitHub Copilot, but access is rolling out gradually. GitHub positions it for quick edits, subagents and terminal work. Its early coding comparison is a provider report, not evidence that every lightweight-model substitution preserves quality.
Citation-ready: GitHub lists Claude Haiku 5.5 as generally available in Copilot with gradual rollout and administrator model policies; its early coding comparison is not an independent workload benchmark.
Evidence boundary: GitHub product announcement and official interface image. No independent speed, token-cost or coding-quality test was performed. Early model comparisons remain attributed to GitHub.
What happened and why it matters
A faster generation is valuable only when the resulting edit survives review. Choose bounded tasks with clear acceptance checks before changing the model for a whole workflow.
Primary evidence
Primary reference: GitHub Copilot Haiku 5.5 changelog. Kaleido Field checked the event date and the article's attributed facts against this source.
| Source date | October 7, 2026 |
|---|---|
| Checked by Kaleido Field | October 8, 2026, CST |
| Source function | AI models -> coding workflow cost and acceptance evidence |
Availability is an account-level observation
GitHub lists Pro, Pro+, Max, Business and Enterprise access across its supported clients, while warning that rollout is gradual. Business and Enterprise administrators can govern the model through Copilot policies. Not seeing it in one client does not establish that the release was withdrawn.
Check your plan, client version and model policy before diagnosing a missing picker entry. Record the model used for each run; silently comparing different selections makes a result difficult to reproduce. The Windows release-state analysis applies the same distinction between an announcement and an observed environment.
Measure accepted work rather than response speed
GitHub describes quick edits, terminal tasks and subagents as intended uses and bills the model at provider list pricing under usage-based billing. The useful trial is a repeatable queue: a small refactor, a targeted test addition and an error diagnosis with known outcomes.
Keep the repository state, tools and acceptance criteria constant. Count retries, human corrections, failed tests and review time alongside latency and metered usage. Our evaluation recommendation is editorial, not a report of tests conducted here. A cheaper first answer can still be a more expensive completed task.
Evidence boundary
GitHub product announcement and official interface image. No independent speed, token-cost or coding-quality test was performed. Early model comparisons remain attributed to GitHub.
FAQ
Does general availability guarantee the model appears in every eligible account immediately?
No. GitHub explicitly describes a gradual rollout and administrator-controlled access.